• Link to Facebook
  • Link to Instagram
  • Link to LinkedIn
  • Link to Youtube
  • Link to X
Call Us Today! 512-640-5750
Data Architect as a Service | Remote DBA Services
  • Services
    • Analytics Architecture
    • Database Architecture
    • Software Architecture
    • Microsoft Fabric Consulting
      • Microsoft Fabric Health Check
  • About Us
    • Testimonials
    • Recommendation Program
    • Jobs
      • Data Engineering Consultant
      • Principal Data Analytics Architect
  • Resources
    • Blog
    • Videos
  • Contact
  • Click to open the search input field Click to open the search input field Search
  • Menu Menu

Programmatically Retrieving MLV Lineage and Refresh Times

Fabric Lakehouse, Fabric Notebooks, Microsoft Fabric, Microsoft Technologies, ProcureSQL, Python

Materialized lake views (MLVs) in Microsoft Fabric are an effective way to implement medallion architecture declaratively, but once you have a pipeline of MLVs in production, you need visibility into whether they’re current. Fabric’s MLV management area gives you a visual lineage and refresh history, but if you want to build automated alerting, logging, or custom tooling, you need to get that information programmatically. This post walks through one way to do that, using a small demo lakehouse built entirely in a Fabric notebook.

Getting lineage from table properties

When you create a materialized lake view, Fabric automatically populates a table property called fabric.source.entities that describes every immediate upstream source. You can retrieve it with SHOW TBLPROPERTIES and parse the JSON payload:

props = spark.sql(f"SHOW TBLPROPERTIES dbo.mlvc").collect()
source_entities_raw = next(
    (row["value"] for row in props if row["key"] == "fabric.source.entities"),
    None
)
sources = [e["tableName"] for e in json.loads(source_entities_raw)]

The payload includes workspace, artifact, and schema context for each source, which means it can support cross-lakehouse lineage scenarios as that capability matures. Combining this across all MLVs in a schema, using SHOW MATERIALIZED LAKE VIEWS IN dbo, gives you the full dependency graph without any hardcoding.

Getting last modified time from source tables

If you have Change Data Feed enabled on your base Delta tables (which you should for optimal MLV refresh anyway) you can retrieve the timestamp of the last committed operation from the Delta transaction log:

history = spark.sql(f"DESCRIBE HISTORY dbo.table1 LIMIT 1").collect()
last_modified = history[0]["timestamp"]

DESCRIBE HISTORY returns the full transaction log in reverse chronological order. LIMIT 1 gives you the most recent entry, which corresponds to the last time data was written to the table. This is more reliable than file system metadata because it reflects committed Delta transactions, not just file touches.

Getting last refresh time from an MLV

MLVs are persisted as Delta tables under the hood, so the same DESCRIBE HISTORY approach works for them too:

history = spark.sql(f"DESCRIBE HISTORY dbo.mlva LIMIT 1").collect()
last_refresh = history[0]["timestamp"]

This gives you the timestamp of the last time the MLV was successfully refreshed, whether that was triggered by a schedule, a notebook, or manually from the portal.

Detecting staleness

With timestamps for both sources and MLVs in hand, you can compare them to determine whether any MLV is out of date. An MLV is stale if any of its upstream sources have a newer timestamp than the MLV itself. Staleness also propagates downstream — if mlvb is stale, then mlvc which depends on mlvb is also stale regardless of its own source timestamps. From there you can write results to a Delta table for historical tracking, feed them into an alerting pipeline, or visualize them inline in the notebook.

Visualizing dependencies in the notebook

Once you have the lineage graph and timestamps as Python objects, you can render an interactive dependency diagram directly in a Fabric notebook cell using displayHTML. Rather than building the diagram from scratch, I used vis.js, a JavaScript network visualization library that loads directly from a public URL at render time with no package dependencies to manage.

vis.js handles node layout, edge routing, and interactivity out of the box, which makes it a practical choice for notebook-based visualization. The diagram is built by serializing the Python lineage dict and timestamp dict to JSON, injecting them into an HTML string, and passing that to displayHTML. vis.js renders a hierarchical left-to-right layout that mirrors data flow direction, with each node labeled with the object name and its last modified or last refresh timestamp. Nodes are color-coded by type — green for base Delta tables, blue for MLVs — and when staleness detection is enabled, any node that needs a refresh turns orange, as do the edges feeding into it. The resulting diagram is interactive — nodes can be dragged to reposition them, the canvas can be scrolled to zoom, and hovering over a node highlights it and its connected edges, which is useful when tracing dependencies in a more complex pipeline.

One thing worth noting: I attempted to use matplotlib first, which is natively available in Fabric notebooks, but I ran into limitations with arrow routing that made the diagram hard to read when nodes were at different vertical positions. vis.js solved that cleanly without any additional setup, as long as the CDN is accessible from your Fabric capacity.

Walkthrough

To demonstrate this end to end, my notebook sets up three base Delta tables and three MLVs with the following dependencies:

  • mlva is sourced from table1
  • mlvb is sourced from table1 and table2
  • mlvc is sourced from mlva, mlvb, and table3

Change Data Feed is enabled on all three base tables so the Delta transaction log captures each write, and CDF is set on the MLVs as well so incremental refresh is available. After setup, the notebook refreshes all three MLVs in dependency order — mlva and mlvb first, then mlvc — to get a clean baseline. You could also refresh them from the Materialized lake views tab on the Lakehouse item in the Fabric portal.

With everything refreshed, parsing fabric.source.entities and DESCRIBE HISTORY across all objects gives us the full lineage graph and a timestamp for every node. At this point nothing is stale, and the baseline diagram reflects that:
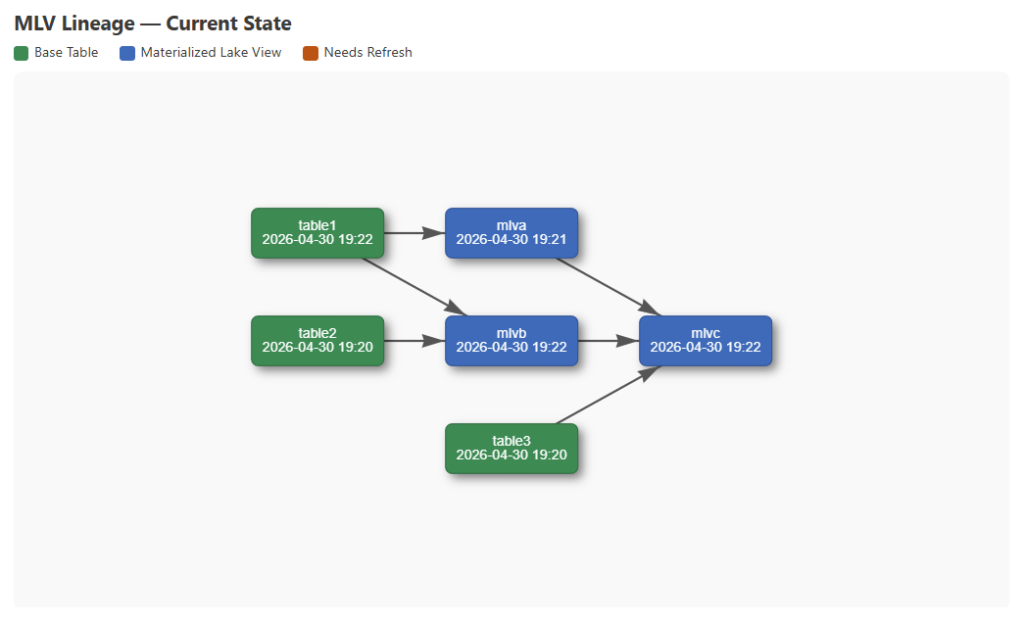
> A vis.js network diagram titled "MLV Lineage — Current State" showing six nodes arranged left to right. Three green nodes represent base Delta tables: table1 timestamped 2026-04-30 19:22, table2 timestamped 2026-04-30 19:20, and table3 timestamped 2026-04-30 19:20. Three blue nodes represent materialized lake views: mlva timestamped 2026-04-30 19:21, mlvb timestamped 2026-04-30 19:22, and mlvc timestamped 2026-04-30 19:22. Arrows show dependencies: table1 feeds into mlva and mlvb, table2 feeds into mlvb, mlva and mlvb feed into mlvc, and table3 feeds into mlvc. All arrows are gray and all nodes are their default colors, indicating that the staleness check has run and no MLVs need a refresh.

Next, three new rows are inserted into table1. That single write makes table1 newer than mlva, mlvb, and mlvc — all three depend on table1 either directly or through a dependency. Re-fetching timestamps and running the staleness check propagates that through the graph, and the updated diagram highlights all affected nodes:
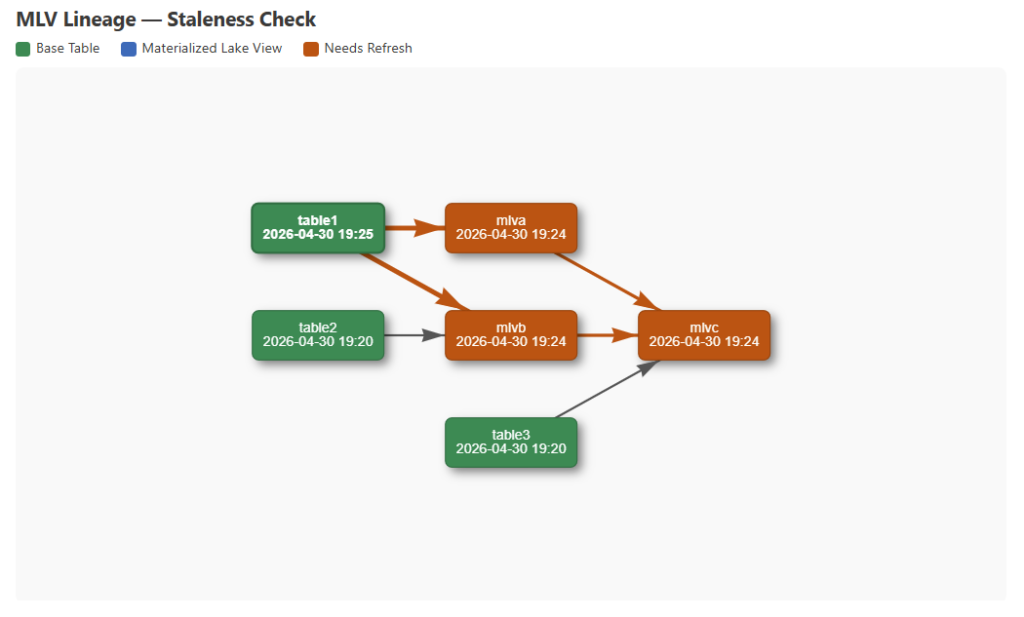
A vis.js network diagram titled "MLV Lineage — Staleness Check" showing six nodes arranged left to right. Two green nodes represent up-to-date base Delta tables: table2 timestamped 2026-04-30 19:20 and table3 timestamped 2026-04-30 19:20. One green node represents table1 timestamped 2026-04-30 19:25, which has a newer timestamp than the MLVs downstream of it. Three orange nodes represent materialized lake views that need a refresh: mlva, mlvb, and mlvc, all timestamped 2026-04-30 19:24. Arrows from table1 to mlva and table1 to mlvb are orange, indicating table1 is the source of the staleness. The arrows from mlva to mlvc and mlvb to mlvc are also orange, showing staleness propagating downstream. The arrows from table2 to mlvb and table3 to mlvc remain gray, as those source tables have not changed since the last MLV refresh.

The Fabric portal already gives you a visual lineage and refresh history for MLVs, but doing this programmatically means you can build on top of it — logging refresh state over time, triggering alerts when MLVs go stale, or embedding a live diagram in an operational notebook. The full notebook is available in my GitHub repo.

What would you do with programmatic access to MLV lineage and refresh state? Let me know in the comments.

The post Programmatically Retrieving MLV Lineage and Refresh Times first appeared on Data Savvy.

April 30, 2026/by Meagan Longoria
https://procuresql.com/wp-content/uploads/2026/04/MLVstale.avif 617 1024 Meagan Longoria /wp-content/uploads/2024/05/Data-Architecture-as-a-Service-with-ProcureSQL.png Meagan Longoria2026-04-30 20:16:072026-04-30 20:16:07Programmatically Retrieving MLV Lineage and Refresh Times
Join Our Newsletter
  Thank you for Signing Up
Please correct the marked field(s) below.
1,true,6,Contact Email,21,false,1,First Name,21,false,1,Last Name,2
Search Search

Blog Categories

  • $150 Challenge
  • Advice
  • Announcements
  • Artificial Intelligence
  • Awards
  • Azure Data Factory
  • C-Level
  • Cloud
  • Community
  • Conferences
  • Data Architecture
  • Data Integration
  • Data Intergration
  • Data Visualization
  • Data Warehousing
  • DBA 101
  • Design
  • Disaster Recovery or High Availability
  • Education
  • Fabric Dev Ops
  • Fabric Lakehouse
  • Fabric Lakehouses
  • Fabric Mirroring
  • Fabric Notebooks
  • Features
  • General
  • Health Checks
  • Lab
  • Microsoft Fabric
  • Microsoft Technologies
  • Newsletter
  • Performance Tuning
  • Power BI
  • ProcureSQL
  • Python
  • Reporting
  • Security
  • SQL Server
  • SQL Server
  • sql server 101
  • SQLServerPedia Syndication
  • syndication
  • The Blog
  • Uncategorized
  • Visual Studio Credit

Tags

#SQLFamily automatic tuning availability group azure backup Backups career Data Governance Data Loss Data Platform DBA Denver Differential Backup Disaster Recovery Fabric Fabric Architecture Full Backup High Availability Houston Marketing Database Administrator Microsoft Microsoft Fabric Microsoft SQL Server mirroring parameter sniffing PASS performance tuning Professional Development query store Recovery Recovery Model Restores Security SQL Saturday SQL Server SQL Server 2017 sql server 2019 SQL Server 2022 sql server 2025 SSMS System Databases Transaction Log Backup tsqltuesday Tuning Wait Stats

Archives

  • September 2026
  • August 2026
  • July 2026
  • June 2026
  • May 2026
  • April 2026
  • March 2026
  • February 2026
  • November 2025
  • October 2025
  • September 2025
  • July 2025
  • June 2025
  • May 2025
  • April 2025
  • March 2025
  • January 2025
  • December 2024
  • November 2024
  • October 2024
  • September 2024
  • August 2024
  • July 2024
  • June 2024
  • May 2024
  • February 2024
  • January 2024
  • November 2023
  • October 2023
  • March 2023
  • January 2023
  • May 2022
  • April 2022
  • November 2021
  • September 2020
  • August 2020
  • April 2020
  • March 2020
  • February 2020
  • January 2020
  • December 2019
  • November 2019
  • September 2019
  • July 2019
  • April 2019
  • November 2018
  • September 2018
  • August 2018
  • July 2018
  • June 2018
  • May 2018
  • April 2018
  • March 2018
  • February 2018
  • January 2018
  • November 2017
  • October 2017
  • August 2017
  • July 2017
  • June 2017
  • April 2017
  • December 2016
  • November 2016
  • October 2016
  • July 2016
© Copyright 2026 - ProcureSQL - 1464 East Whitestone Blvd., Suite 1902 Cedar Park, TX 78613, USA
  • Link to Facebook
  • Link to Instagram
  • Link to LinkedIn
  • Link to Youtube
  • Link to X
Scroll to top Scroll to top Scroll to top
Manage Consent
To provide the best experiences, we use technologies like cookies to store and/or access device information. Consenting to these technologies will allow us to process data such as browsing behavior or unique IDs on this site. Not consenting or withdrawing consent, may adversely affect certain features and functions.
Functional Always active
The technical storage or access is strictly necessary for the legitimate purpose of enabling the use of a specific service explicitly requested by the subscriber or user, or for the sole purpose of carrying out the transmission of a communication over an electronic communications network.
Preferences
The technical storage or access is necessary for the legitimate purpose of storing preferences that are not requested by the subscriber or user.
Statistics
The technical storage or access that is used exclusively for statistical purposes. The technical storage or access that is used exclusively for anonymous statistical purposes. Without a subpoena, voluntary compliance on the part of your Internet Service Provider, or additional records from a third party, information stored or retrieved for this purpose alone cannot usually be used to identify you.
Marketing
The technical storage or access is required to create user profiles to send advertising, or to track the user on a website or across several websites for similar marketing purposes.
  • Manage options
  • Manage services
  • Manage {vendor_count} vendors
  • Read more about these purposes
View preferences
  • {title}
  • {title}
  • {title}