https://procuresql.com/wp-content/uploads/2026/04/Data-Architecture-Breaks.avif639637John Sterrett/wp-content/uploads/2024/05/Data-Architecture-as-a-Service-with-ProcureSQL.pngJohn Sterrett2026-09-01 01:59:232026-09-01 01:59:23Data Classification for HIPAA-Aligned Security in SQL Server and Azure SQL
Fabric deployment pipelines look like they solve CI/CD for Fabric content, especially for people who prefer a GUI over writing code to handle deployments, but the implementation has enough structural gaps that they fall apart for several real deployment workflows. Even when they do work, the UI isn’t always intuitive.
Every piece of active software carries a backlog of feature requests and known limitations, and deployment pipelines get new capabilities on a regular basis. Everything below reflects how deployment pipelines behave as of August 2026. Some of it may have changed by the time you’re reading this, so check Microsoft’s docs for the current state before you plan around any of these.
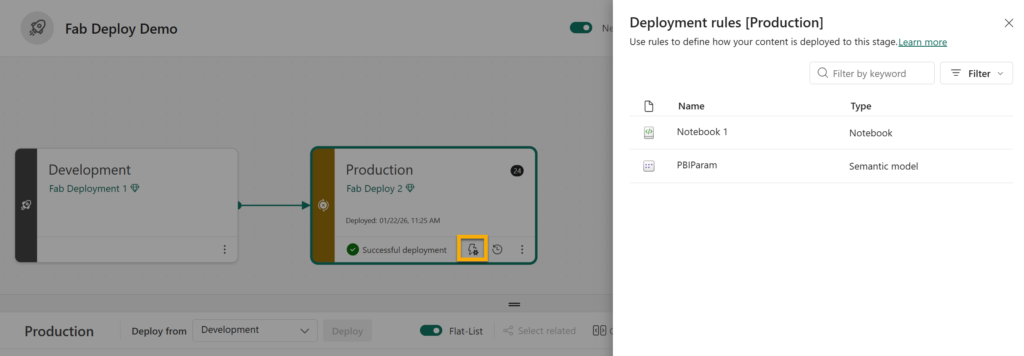
A Fabric deployment pipeline moving items from Development stage to Production stage. Two items are shown on the right as candidates for deployment rules, but you can’t actually see whether a rule has been set
The List
The required permissions are not obvious, and you can’t see all the permissions in one place. Pipeline access and workspace access are managed completely separately, and you need both to do anything. A deployment pipeline has exactly one role, Admin. There’s no Member or Contributor tier the way a workspace has, and Pipeline Admin by itself only lets you view, share, edit, or delete the pipeline. It grants no access to workspace content. To actually deploy, you separately need at least Contributor on both the source and target workspace for that stage. And to create or edit a deployment rule specifically, there’s a third requirement stacked on top of those two: you have to own the item you’re setting the deployment rule for. So permission to do anything meaningful is checked across three different places: pipeline role, workspace role, and item ownership. There’s no single view that shows you all three at once.
Deployment rules require a deployment before you can set them. You can’t set a deployment rule (a parameter override, a connection string swap, anything) until after an item has already been deployed once through the pipeline. That means the very first deployment always carries whatever configuration existed in the source workspace, with no way to redirect it. You deploy, then go set the deployment rule, then deploy again for the deployment rule to actually take effect. If you care about Dev connection strings and config never touching Test or Prod, that first pass is exactly the wrong behavior.
The deployment rules UI is hard to find, and you can’t see more than one deployment rule at a time. Setting a deployment rule isn’t self-explanatory. The deployment rules interface isn’t easy to find in the first place. There’s no view that shows you all the deployment rules configured across a stage at once, either; you have to go into each item individually to see its deployment rules.
Paginated report connections can’t always be overridden by a deployment rule. Data source deployment rules do exist for them, but only when the connection is a non-Power-Query-Online type, a direct connection string, like SQL Server or Oracle, rather than a standard Fabric “Get Data” connection. If a paginated report’s data source is PQO-based, there’s no deployment rule that can override it; you’re stuck manually repointing it in each stage. And even when a deployment rule does apply, deploying a paginated report with a data source deployment rule attached means you can no longer open that report in Power BI Report Builder afterward.
Variable libraries don’t work the same way across item types, and semantic models don’t support them at all. They’re Fabric’s newer mechanism for handling environment-specific configuration, and they do eliminate the need to hardcode values directly into a deployment rule. You reference a variable instead of typing a literal per environment, but how that reference actually resolves differs by item type. Pipelines reference the variable directly and pick up whatever value is active in that workspace at runtime. Most other item types need a deployment rule tied to the variable to pick up a change; the value only updates when you deploy, not just because the active value set changed. A variable library also isn’t written once and magically available everywhere. It’s scoped to a single workspace, and it deploys through the pipeline like any other item, carrying every value set along with it to every stage. Changing a variable’s structure (adding, deleting, or renaming a variable or a value set) doesn’t take effect anywhere until you deploy the library through the pipeline again. The only thing that’s actually local to each stage, untouched by deployment, is which value set is marked active there. And that’s assuming your item type is even eligible. Semantic models simply aren’t supported for variable libraries at all. The supported list covers pipelines, notebooks, dataflows (gen 2), copy jobs, lakehouse shortcuts, user data functions, and plan items.
Pairing breaks if you manually create a folder in the target, or if you have to delete and recreate a corrupted item. Deployment pipelines track whether an item in one stage is “paired” with its counterpart in the next stage, and pairing is what determines whether a deployment overwrites that item or creates a duplicate copy alongside it. If you manually create a folder in the target workspace ahead of time and then try to deploy items from the source into a matching folder, deployment fails. Folders count as part of an item’s path for pairing purposes, and a folder created directly in the target, rather than by the pipeline itself, was never paired to begin with. The fix is to delete the folder you created manually and let the pipeline create it during deployment instead. The same underlying problem shows up when an item gets corrupted: deleting and recreating it makes it a new item as far as pairing is concerned, so it comes back unpaired even with the identical name. You’re stuck manually re-syncing it — deleting the counterpart in the target stage and redeploying, or unassigning and reassigning the workspace — rather than the pipeline just picking the connection back up. And it doesn’t stop at the item itself — anything that referenced it breaks too. A report connected to it or a shortcut pointing at it held a reference to the old item’s identity, and that identity is gone. They don’t automatically find their way to the replacement; you have to manually reconnect every one of those references on top of re-syncing the pairing itself.
A workspace can only belong to one pipeline, in either direction. It’s a strict one-to-one relationship. Each pipeline stage holds exactly one workspace, so multiple development workspaces can’t all feed into a single shared target. It runs the other way too: a shared or common-code workspace can only be a stage in one deployment pipeline at a time, so it can’t feed into more than one downstream chain of workspaces.
Deployment pipelines only work at the whole-item level for lakehouses and warehouses, and several sub-items get no support at all. There’s no option to deploy just one table’s schema and leave the rest alone; it’s the entire lakehouse or warehouse, or nothing. If you need that kind of granularity, you can work with the SQL database project directly or write your own scripts, but either way that happens outside the deployment pipeline itself. The SQL analytics endpoint that sits over a lakehouse is a step further than that. Microsoft’s documentation confirms Git integration and deployment pipelines both exclude the SQL analytics endpoint item entirely. Any views or stored procedures you build directly on it aren’t tracked and aren’t deployed; you have to recreate them by hand in every stage. The same gap shows up with mirrored databases: Microsoft’s CI/CD documentation for mirrored databases states that only the mirrored database item itself is tracked in Git, while the SQL analytics endpoint and any views you’ve created are excluded.
No post-deployment actions. There’s no hook to run a script or action automatically after a deployment completes, nothing like a predeploy/postdeploy step the way Azure DevOps or GitHub Actions offer. If you need to trigger a notebook, refresh a semantic model, or run any cleanup step right after content lands in a stage, that has to be a separate step triggered outside the pipeline.
No approvals or gated pipeline executions. There’s no way to require sign-off before a deployment proceeds. No pre-deployment approval, no required reviewer, no gate that pauses the pipeline until someone signs off. This means all reviews and all communication about items for deployment happen outside the deployment pipeline interface entirely, with nothing tying that conversation back to the actual deployment event.
Alternatives
None of this means you’re stuck with deployment pipelines as they are. There are a few different ways to work around most of what’s above.
Script around the GUI, keep the pipeline. Fabric exposes APIs for most of what deployment pipelines do, so you can drive the same underlying pipeline programmatically instead of clicking through the UI, including creating the pipeline, assigning workspaces, and deploying stage content. That removes a lot of the pain that’s specific to the interface itself, since you’re never actually opening that screen. Two things still won’t get fixed this way. Deployment rules seem to have no REST API at all, so you’re still setting those up by hand no matter how much of the rest you script. And pipeline access still requires someone to explicitly share the pipeline with each person, which is a separate action from assigning any workspace role and has no API either; the only automatic path to Pipeline Admin is being the person who created the pipeline in the first place.
Wrap it in another CI/CD tool. If what you actually want is approvals, gates, or a post-deployment script, and you’re fine keeping deployment pipelines for the item movement itself, you can put a tool like Azure DevOps around it. The external tool handles the approval gate and the post-deployment step, and calls the Fabric deployment pipeline API as one stage in its own pipeline.
Skip deployment pipelines entirely. You can script the whole deployment yourself against the Fabric APIs, with no deployment pipeline object involved at all. And you don’t have to write that from scratch. fabric-cicd is a Microsoft-maintained Python library built for exactly this. It deploys Fabric items from a Git repo into a workspace, so you don’t have to build and maintain that integration yourself. That’s actually how I started doing my own deployments: writing that scripting logic in Fabric notebooks. Eventually I wanted a UI on top of it instead of editing notebook parameters (to be more user-friendly for my clients), so I built a Fabric app using Rayfin, Microsoft’s managed backend-as-a-service SDK for building apps on Fabric. This Fabric API approach isn’t limited to notebooks or a custom app. The same scripting logic can just as easily become an AI skill, letting an agent handle your deployments for you.
None of these options are free. Deployment pipelines as they are remain the simplest choice if you want to stay low-code, but every gap in this post is still your problem. Put Azure DevOps or GitHub Actions around them instead, and you get real gates and post-deployment automation, at the cost of a second system to maintain and an integration point between it and Fabric. The most flexible path is building your own scripts, app, or AI skill. But now you own the build and the upkeep, and even that has a ceiling, since the public Fabric APIs have their own gaps. Which trade-off makes sense depends on the benefits realized and how much of that effort your team wants to take on.
What gaps in deployment pipeline functionality have affected you the most? And if you’ve moved to an alternative, which one, and how’s it working out? I’d love to hear about it in the comments.
The post 10 Things I Hate About Fabric Deployment Pipelines— And Some Alternatives first appeared on Data Savvy.
https://procuresql.com/wp-content/uploads/2026/08/Deployment-Rules.avif5351536Meagan Longoria/wp-content/uploads/2024/05/Data-Architecture-as-a-Service-with-ProcureSQL.pngMeagan Longoria2026-08-21 17:10:392026-08-21 17:29:4810 Limitations of Fabric Deployment Pipelines And Some Alternatives
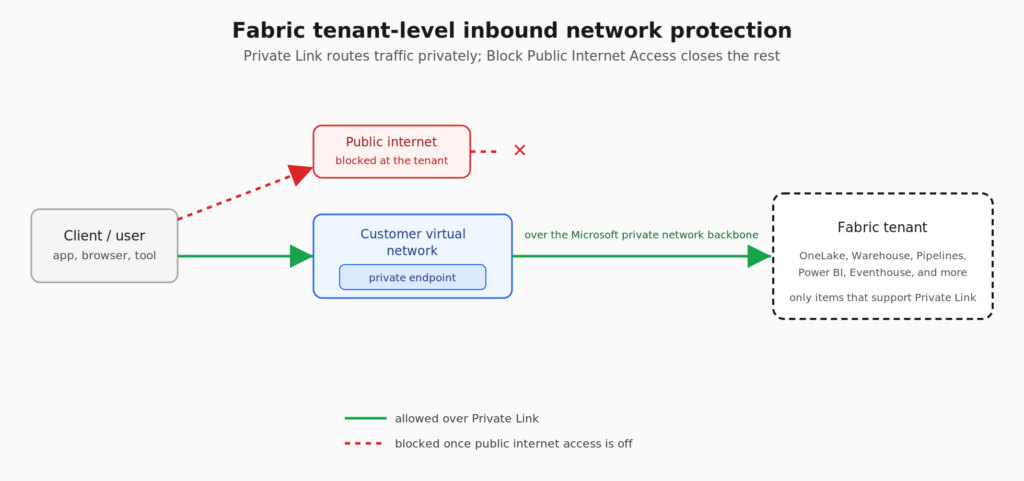
Fabric’s inbound network protection gives you two tenant-level controls: Private Link, which routes traffic through your virtual network instead of the public internet, and Block Public Internet Access, which closes the public internet off entirely once Private Link is in place. Together they look like the obvious move if you’re trying to get a data platform off the public internet. Flip two settings, close off the internet, ship a more secure platform. That’s the pitch.
As of July 2026, it isn’t that simple. Enabling them changes how a specific, and fairly long, list of Fabric features behaves. Some keep working but in a degraded state; others stop working entirely. None of it is undocumented. It’s just spread across a dozen different Microsoft Learn pages, and almost nobody reads all of them before changing a tenant setting. Here’s what stands out on that list.
The ones that redesign your architecture
I’d flag on-premises data gateways first. Turn on Private Link, and you can no longer register a new gateway or migrate, restore, or take over an existing one. Every Fabric item that leans on an on-premises gateway is exposed to that: Dataflow Gen2, pipelines, semantic model data sources, mirroring. A virtual network data gateway is the only supported replacement, and if your organization has gateway infrastructure built around the on-premises gateway, moving it to a VNet data gateway is its own migration project.
Mirroring has an extra problem on top of that. A virtual network data gateway looks like it should fix this one, and it doesn’t. If you’re mirroring a SQL Server 2016 through 2022 database into Fabric, whether it’s on-premises, on an Azure VM, or on another cloud, that mirroring uses Change Data Capture under the hood, not the change feed mechanism SQL Server 2025 uses. Microsoft’s Private Link exception list for mirroring is short: open mirroring, Azure Cosmos DB, Azure SQL Managed Instance, SAP, SharePoint List, and SQL Server 2025 mirroring specifically. CDC-based mirroring for 2016–2022 isn’t on it. Turn on Block Public Internet Access, and active mirrors for those databases pause while new ones can’t be started.
That gateway solves connectivity to the source, which is a different problem from the one Block Public Internet Access creates. The restriction isn’t about whether Fabric can reach your database. It’s about which mirroring mechanism Microsoft has explicitly cleared for Private Link, and CDC-based mirroring isn’t one of them.
The realistic options are migrating the affected databases to SQL Server 2025, where native mirroring is on the supported list; switching to open mirroring, which means writing and maintaining your own publisher that pushes data into the OneLake landing zone; or dropping mirroring for those databases entirely and building the ingestion yourself with a pipeline or a notebook pulling from the source on a schedule. None of these is a small decision, and none is one you want to be making after the setting is already flipped and mirrors have already paused.
There’s more that forces a rethink. If any part of your build leans on a Fabric Data Warehouse, know that a pipeline’s Copy Data activity can’t move data into or out of it at all under Private Link.
Eventhouse loses even more ground: it can’t ingest from OneLake, can’t be the target of a shortcut, can’t be connected to a pipeline, and loses both queued ingestion and T-SQL support. If real-time analytics is part of the plan, Private Link takes most of Eventhouse’s usefulness with it, which usually means designing around it from the start rather than bolting it on later.
Purview is affected too. Data Map scanning of Fabric is unsupported over Private Link, so if Purview is how you catalog and govern this data, that scanning simply stops. The OneLake Catalog’s Govern tab, Fabric’s own governance surface, stops working as well. Separately, Purview Information Protection also breaks in Power BI Desktop: sensitivity labels stop resolving, the Sensitivity button grays out, and pbix decryption fails. That last one only matters if the label is tied to a Purview publishing policy that encrypts the file. When that’s the case, Desktop has to call out to the rights management service to decrypt the file before it’ll open at all, and without that call, it just won’t open. Sensitivity labeling in Desktop depends on Exchange Online Protection and Azure Information Protection behind the scenes, so opening service tags for those two services restores label resolution and pbix decryption there. It’s a client-side network exception, though, not Fabric itself gaining Private Link support for Purview Information Protection. If you’re actually relying on Purview to govern this data, neither of these is a detail to find out about after go-live.
If you were planning on using cross-tenant OneLake shortcuts to collaborate with vendors, partners, or customers, those are not supported over Private Link.
The capabilities you lose
Below that tier, but still enough to change what you can build, is a set of items where the setting doesn’t just reroute traffic, it removes product functionality outright.
The first Spark job or Lakehouse table operation you run provisions a managed VNet for the workspace it runs in, which disables the prewarmed starter pools Fabric normally uses to get notebooks running fast. That managed VNet allocation is permanent, so once it happens, you lose the ability to migrate the workspace to a capacity in a different region.
Email subscriptions for Power BI reports fail across every subscription type. The paginated report side of that is the one to take seriously. People often choose paginated reports over interactive ones for exactly this reason. They’re built for pixel-perfect print and PDF output. They also export to Excel, Word, and CSV. And they can be emailed on a schedule to people who never log into Power BI at all. If that’s the requirement you’re building for, losing subscriptions doesn’t degrade the report. It removes the reason it exists.
Data agents can’t use Kusto/Eventhouse, semantic models, or mirrored databases as sources under Private Link. Only lakehouse, warehouse, and Fabric SQL Database sources still work.
Copilot in Power BI is unsupported in a Private Link environment. That covers the chat pane for Q&A over a semantic model, report and visual creation from a prompt, DAX query generation and explanation, measure descriptions, and narrative summaries in reports and email subscriptions.
The annoyances
Then there’s the stuff that hits lesser-used features. Each one still stops working completely, not just gets worse, but none of it is going to stop a project on its own.
Exporting a Power BI report to PDF or PowerPoint stops working. Power BI usage metrics start returning partial data, or none at all. Power BI’s Publish to Web stops working too, though plenty of organizations already have that disabled at the tenant level for unrelated reasons. Externally hosted images referenced in a Power BI report fail to load for the same reason: resolving them means an outbound fetch, and that’s exactly what Block Public Internet Access blocks.
If a semantic model or Dataflow Gen1 is built to pull from another semantic model or dataflow as its source (a composite model layered on an existing imported semantic model, for example), that connection breaks, because it relies on a network path that Block Public Internet Access blocks.
Individually, none of these is a reason to abandon the plan, though a couple of them, like the composite model case above, mean planning around them if that’s part of your design.
A couple of things are worth planning around before you start building. Trial capacities don’t work over Private Link at all. And a freshly created F-SKU capacity won’t support Private Link until its endpoint propagates into the private DNS zone, which can take up to 24 hours, so a capacity you just spun up can look broken when it’s really just waiting on DNS to catch up.
Why the gap exists
Based on how Private Link and Block Public Internet Access are documented to work, public endpoints appear to be Fabric’s baseline path for a lot of its traffic, since anything that doesn’t support Private Link either falls back to the public internet or gets blocked outright. Private Link and Block Public Internet Access change that at the tenant level, but not every service was built to work within that constraint. The list above is what happens when a tenant-wide security setting gets layered onto services that predate it.
What to do instead
If the list above outweighs what Private Link and Block Public Internet Access actually buy you in security, there are alternatives worth knowing about, none of them a perfect substitute, all of them worth understanding before you commit to one.
Lean on Conditional Access instead of network blocking. Every Fabric request already authenticates through Microsoft Entra ID. A policy requiring MFA, a compliant device, and sign-in only from named locations controls who gets in and from where, without touching Fabric’s network configuration. None of the breakage described earlier in this post happens with this approach. The tradeoff: traffic still crosses the public internet, encrypted but not privately routed. If your actual requirement is that data never touches the public internet, this doesn’t satisfy it. If the requirement is about controlling access, it usually does.
Protect the data, not just the path. Sensitivity labels tied to a Purview publishing or protection policy can encrypt content in a way that’s bound to identity, so where that’s set up, only authorized users can open the file, even if it crosses the public internet. That’s not automatic for every label. It depends on the policy attached to it. Pair that with Purview DLP policies scoped to Power BI and Fabric: they can flag a sensitive item with a policy tip, alert admins, or restrict access to it entirely, evaluated against the item’s data and labels, not the network path it travels.
One thing worth clarifying: workspace-level protection isn’t a lighter-weight version of the tenant-level decision. It has its own use cases, but it trades one set of limitations for another, plus adds more networking infrastructure to build and maintain.
Go in with eyes open
None of this is an argument against securing the tenant. It’s an argument for being specific about what you’re actually protecting against: unauthorized access, data exfiltration, or a hard requirement that data never leave a private network. Those are three different problems with three different tools, and Private Link plus Block Public Internet Access is only the right answer to one of them. Read the exception lists before you flip the switch, not after a mirror pauses in the middle of a project.
As always, the limitations will change as Fabric receives updates. Be sure to check the documentation for the latest information.
Series: Building a SQL Server Always On Lab in Azure
Before You Begin
This is the first post in the series. There are no prerequisites beyond an active Azure subscription with the Visual Studio credit activated. If you haven’t done that yet, the next post covers it as its first step.
Who Is This Series For
I’m a DBA with about ten years of experience. I feel like know SQL Server inside and out. Whether it is execution plans, AG internals, backup strategies, or something in between, I feel comfortable with all of it. What I’ve been less confident about is a lot of what surrounds SQL Server. It could be the networking, the Windows configuration, or the Active Directory setup that the sysadmin team always handled while I waited for a server to be handed to me.
This series is my attempt to understand the full picture by building it myself, from scratch, in Azure and writing down everything I learn along the way.
If you’re a DBA, this will hopefully teach you enough Windows administration and Azure networking to stop feeling like a passenger when infrastructure conversations happen. If you’re a sysadmin, the SQL Server sections will explain why DBAs make the configuration requests they do, not just what those requests are. If you’re on the security side of things, the series tries to make a point to call out every decision that has a security implication and explains the reasoning, not just the steps.
My goal is for anyone in a tech background to be able to do this just like me, I try not to assume you’ve done any of this before and explain everything.
So What Are We Building
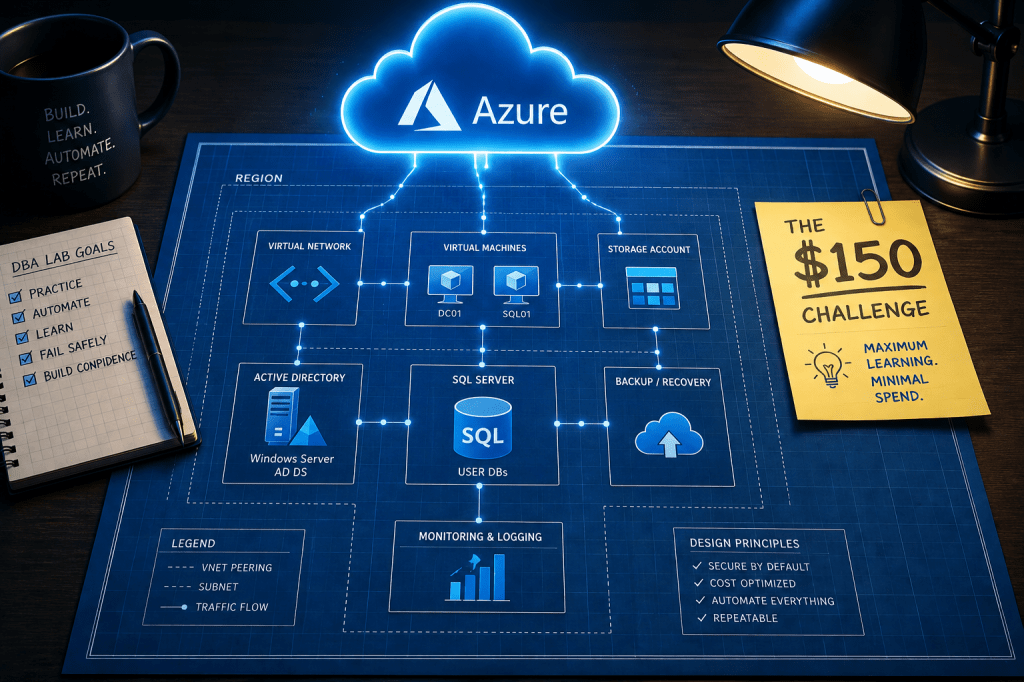
By the end of this series, we’ll have a Management/Monitoring server and a fully functional SQL Server Always On Availability Group running in Azure, built on a real domain, with proper networking, service accounts, and backups. The environment will look like this:
Machine
Role
Size
Private IP
JUMPBOX01
Management/Monitoring Server
B2s
10.10.0.4
DC01
Domain Controller and file share witness
B2s
10.10.1.4
SQL01
SQL Server Primary
D2s_v3
10.10.2.4
SQL02
SQL Server Secondary
D2s_v3
10.10.2.5
All four machines live inside a single Azure Virtual Network (vnet-pcsql-lab-eus-001, 10.10.0.0/16) in East US, divided into dedicated subnets by role. The only machine with a public IP is JUMPBOX01, and that IP is locked to your home IP address via a Network Security Group. Everything else is completely private.
The domain is procuresql.local. The company in all examples is Procure SQL.
The SQL nodes will be members of a Windows Server Failover Cluster (SQLCluster01) with DC01 providing the third vote via a file share witness at \\DC01\SQLWitness. The Availability Group and listener will follow the naming pattern we’ve established for the series, but we’ll get to that later in this page.
Backups go to Azure Blob Storage. Service accounts are Group Managed Service Accounts. No plaintext passwords in scripts, anywhere.
Why Azure? Why $150?
The Visual Studio subscription credit gives you $150 per month in Azure resources. It resets monthly, it doesn’t roll over, and if you go over the limit Azure will suspend your subscription rather than charge you, which makes it a hard ceiling that forces you to actually think about cost, which is a valuable skill in itself.
Here’s what this environment costs assuming 9 hours of uptime per day (8am to 5pm), 22 working days a month, with auto-shutdown handling the rest. If you don’t use it the entire work day and/or if you don’t use it every work day, these estimated costs will be lower.
Resource
Notes
Est Monthly Cost
JUMPBOX01 – B2s
9hrs/day × 22 days @ $0.042/hr
$8
DC01 – B2s
9hrs/day × 22 days @ $0.042/hr
$8
SQL01 – D2s_v3
9hrs/day × 22 days @ $0.188/hr
$37
SQL02 – D2s_v3
9hrs/day × 22 days @ $0.188/hr
$37
OS Disks (x4 Standard SSD)
Disks are billed at rest, this covers each VM’s C drive
$8
SQL Data Disks (x2 Premium SSD P10)
One per SQL AG Node
$10
SQL Log Disks (x2 Premium SSD P10)
One per SQL AG Node
$10
Blob Storage for backups
50GB of Azure Locally Redundant Storage (LRS)
$3
Internal Load Balancer and Public IP
ILB for the AG Listener, Static Public IP for JUMPBOX01
$7
Key Vault, VNet, NSGs
Free Tier
$0
Total
$138
A note on the SQL disks: unlike a traditional active/passive failover cluster where the storage floats between nodes, an Always On AG keeps a completely independent copy of every database on each replica. SQL01 and SQL02 each need their own data disk and their own log disk.
The $12 of headroom is tighter than it looks. Disks are billed whether the VM is running or not, so the ~$28 in disk costs hits every month regardless of how disciplined you are with uptime. The budget alert we’ll set in the next post will warn you at $140, so at $138 estimated, a few extra hours of VM uptime in a given month is genuinely enough to clip the ceiling. Which brings me to the final note on cost.
Auto-shutdown is non-negotiable here. A single D2s_v3 left running 24/7 for a full month costs around $137 by itself. Two of them running wide open and you’ve blown the budget before you’ve touched a SQL setting. We’ll configure auto-shutdown on every VM at deploy time, not as an afterthought.
How The Series Is Structured
I am trying to break this down so that each post covers a single topic. Every post follows the same structure:
Why we’re doing this – the reasoning behind the decision, not just the steps
How to do it – step by step, with individual commands and code blocks inline as you read
How to verify it worked – because “it didn’t throw an error” is not a test
Throughout each post, individual steps are broken into small code blocks so you read what you’re about to do, do that one thing, and then move on. At the end of every post is a consolidated PowerShell script that runs everything from that post in one shot, which I always found to be useful once you’ve read through it once and understand what it’s doing.
Posts reference each other. If something was set up in an earlier post, you’ll see a link like “we set the static IPs back in post 6” so you can jump back if you need a refresher without the current post re-explaining it.
If you’re following along from the beginning, each post’s testing section produces a state that the next post assumes. If something breaks, the testing sections are your breadcrumb trail back to where things went sideways.
Some Additional Notes
Naming Conventions
I have a naming convention for things that works for me, it might not work for you. But if you want to try to follow it, every resource in this series follows this one. This table is your reference for the entire series.
Thing
Convention
Example
Servers
ALLCAPS##
SQL01, DC01, JUMPBOX01
Domain (FQDN)
procuresql.local
NetBIOS
PROCURESQL
Databases
PascalCase
HRSystem, WidgetTracker
AG name
AppNameAG (max 14 characters)
HRSystemAG
AG listener
AppNameAGL (max 15 characters)
HRSystemAGL
Cluster
SQLCluster01
File Share Witness
\\DC01\SQLWitness
Service Accounts
svc_ServiceName (gMSA)
svc_SQLEngine$, svc_SQLAgent$
Resource Group
rg-{workload}-{env}
rg-pcsql-lab
VNet
vnet-{workload}-{env}-{region}-{instance}
vnet-pcsql-lab-eus-001
Subnets
snet-{role}-{env}-{instance}
snet-mgmt-lab-001
Storage Accounts
st{type}{workload}{env}{instance}
stblobbackuplab001
Network Security Groups
nsg-{subnet}-{env}-{instance}
nsg-mgmt-lab-001
Why A File Share Witness Instead Of A Cloud Witness
This comes up quickly when you start reading about Windows Server Failover Clustering in Azure. Microsoft’s own documentation often defaults to Azure Blob Storage as the cluster quorum witness, and it works fine. We’re doing something slightly different: using DC01 as a file share witness instead.
There are two reasons. First, we have a domain controller, so we have a third machine that can serve as the tiebreaker vote without adding cost. This also gives you insight into how a typical on prem setup would work. Second and more importantly for this series, understanding why WSFC needs a third vote, and how a file share witness actually provides it, teaches you more about quorum mechanics than pointing a script at a blob container does. The manual approach here is intentional.
What’s Next
Post 2 will be Subscription Setup & Cost Guardrails is where we start actually touching Azure. We’ll activate the Visual Studio credit, create the resource group, set up budget alerts, and configure the auto-shutdown policy that keeps us inside the $150 ceiling for the rest of the series.
/wp-content/uploads/2024/05/Data-Architecture-as-a-Service-with-ProcureSQL.png00Kyle Wagner/wp-content/uploads/2024/05/Data-Architecture-as-a-Service-with-ProcureSQL.pngKyle Wagner2026-07-01 19:33:162026-09-01 02:24:53The $150 Challenge: What We’re Building and Why
If you’ve been watching AI roll through the data community and thinking, “this seems useful, but I have no idea where to start,” this post is for you. If you have ethical objections to using AI, follow your convictions — this post isn’t here to convince you otherwise. My position these days is that AI use is inevitable in this industry, so I want to understand how to use it carefully and effectively while advocating for mitigation to the societal and environment damage that it causes. So if you’re curious, read on. Including AI in your Power BI development process doesn’t require a dramatic leap. It’s a progression. Start small, build confidence, add more capability when you’re ready.
I use examples from both Claude Code and Github Copilot in this post. I currently prefer Claude and Claude Code as my AI harness, but everything described here applies broadly to other generative AI tools. The principles are the same; only the menus change.
Before diving in: make sure you understand your organization’s policies around AI tool use. Even pasting a DAX measure or a data model description into a chat interface is sharing potentially sensitive business logic with an external service, and the concerns only grow as AI tools gain more direct access to your files and environment. The European Data Protection Board’s AI Privacy Risks and Mitigations in LLMs is a vendor-neutral reference for understanding what’s at stake, and worth a read before having that conversation with your security or compliance team.
Let’s walk through five stages, from a simple chat window to an AI-assisted workflow.
Note: Both AI tooling and Power BI capabilities evolve quickly. The specifics here are accurate as of June 2026, but some details may have changed by the time you’re reading this.
Crawl: Ask Questions in an AI Chat Interface
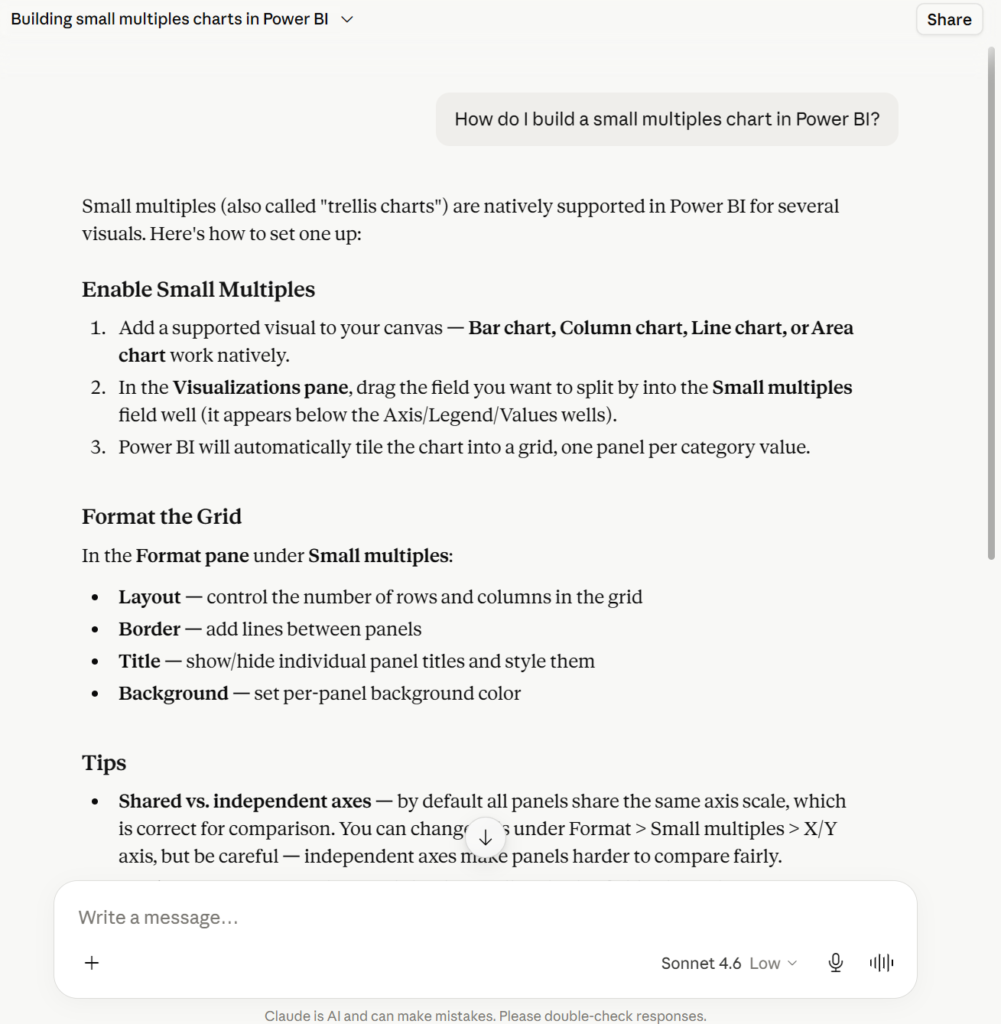
You open Claude, ChatGPT, or your preferred AI chat. You ask it a question. You use the answer.
This is the easiest place to start, and it can be genuinely useful. You’re not giving the AI access to your files or your environment; you’re just asking it things.
Some examples that may work well at this stage:
“How do I write a DAX measure that calculates rolling 12-month sales?”
“How do I build a small multiples chart in Power BI?”
“Why is my RANKX measure returning the same value for all rows?”
“Create a Power BI theme file that uses these hex colors: …”
You paste the DAX into Power BI Desktop yourself or follow the steps the AI outlines. The AI never touches your files; it’s just a resource you can query.
Using Claude chat in a browser window to answer a Power BI question
Always validate the output. AI is often wrong, particularly when it lacks context about your specific setup. It’s also non-deterministic: ask the same question twice and you may get a different answer. Test DAX measures against known values, verify steps actually exist in the UI, and don’t assume a confident-sounding answer is a correct one. Accuracy also varies with how you use the chat. Short, focused questions with fresh context tend to produce more reliable answers than long, winding conversations where the AI may lose track of earlier details or carry forward incorrect assumptions.
It’s worth starting here because it builds your intuition for how to prompt AI effectively. Learning to give clear context (“I have a fact table with a DateKey column and a Calendar table with a Date column joined on…”) makes a real difference in answer quality, and that skill pays off as you add more capabilities.
You’re ready for the next stage when you find yourself copy-pasting a lot, or wishing the AI could just see what you’re working with.
Walk: Bring AI Into Your Code Editor
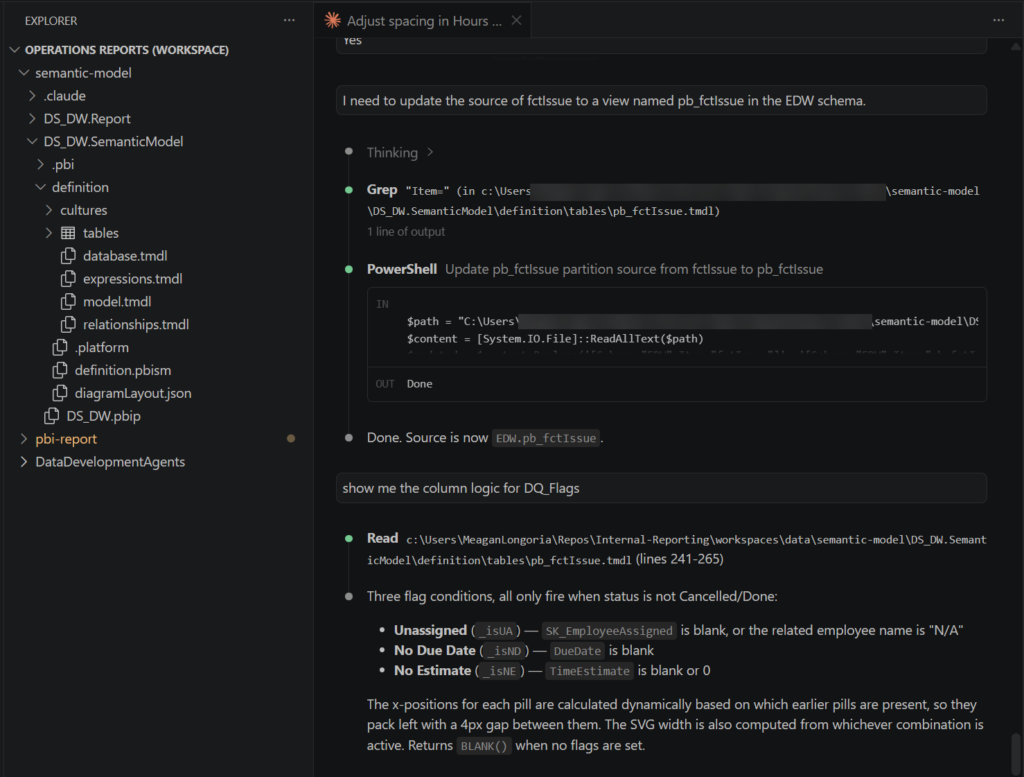
You set up Visual Studio Code with an AI extension, open your Power BI project in PBIP format, and let the AI suggest or make changes, with your approval before anything is applied.
Using Claude Code in Visual Studio Code to update a semantic model
This is where things get a lot more powerful. A few important things to know:
You Need PBIP Format
Power BI Desktop’s default .pbix format is a binary file, so AI tools can’t read or modify it meaningfully. The PBIP (Power BI Project) format saves your report and semantic model as human-readable text files (TMDL for the model, PBIR-format JSON for the report). This is what makes AI-assisted editing possible.
To enable it: in Power BI Desktop, go to File > Options and settings > Options > Preview features and turn on Power BI Project (.pbip) save format.
AI Suggests, You Approve
In VS Code with an AI extension like GitHub Copilot or Claude Code, the AI proposes changes that you can review before accepting them. Nothing changes without your approval. Think of it this way: AI as a very fast first draft, you as the editor with final say.
This is also where planning mode is useful. Before writing a single line, you can ask: “I need to add a chart to the Sales Overview page showing which products have the highest gross margin this quarter.” The AI will lay out a plan; you can push back or refine it, then execute when you’re ready.
Tip: Give AI References
AI works much better when it has context. A few things worth providing:
Point the AI to your existing TMDL files so it can read your naming conventions, relationships, and calculation patterns directly from the model.
Link to the TMDL or PBIR schema documentation. Microsoft Learn has docs on TMDL and the PBIR report folder format, and pointing AI to the schema encourages it to avoid hallucinating property names.
Share a snippet from an existing report in PBIR format so the AI learns how you’ve structured visuals, pages, and filters.
The more context you give, the fewer iterations you need to achieve useful output. You’re ready for the next stage when you want the AI to do things autonomously — query documentation, check schemas, look things up — without you having to manually feed it everything.
Run: Add Skills and Connect to MCP Servers
You install skills and connect your AI harness to MCP (Model Context Protocol) servers, giving it purpose-built capabilities and the ability to take actions on your behalf.
Skills are packaged capabilities that teach the AI how to perform specific tasks. Your AI harness likely comes with some built-in skills, but they likely are not specific to Power BI. MCP servers connect your AI harness to external tools and live data. Together, skills and MCP servers let the AI do significantly more than suggest text in an editor.
Installing Skills and Connecting MCP Servers in VS Code
For GitHub Copilot CLI, skills are installed as plugins from a marketplace. To get the Power BI skills, first register the Microsoft Fabric marketplace, then install the authoring bundle:
Once installed, those skills are active in Copilot conversations in your project. No further configuration needed to start using them.
For MCP servers, VS Code with Copilot connects to them through a .mcp.json file in your workspace. The Power BI local MCP server runs on your machine and works with a running instance of Power BI Desktop, or with your PBIP files directly. The Power BI authoring plugin automatically registers the Power BI modeling MCP server on your machine.
If you don’t like the Microsoft-provided plugins (they are fairly new and still in preview), there are others available in the community.
Once skills and MCP servers are in place, the AI knows how to work with Power BI assets and has the tools to act. You spend less time explaining the territory and more time reviewing what it did.
The key difference from the previous stage: the AI has agency within the boundaries you set. It’s not just suggesting text; it’s taking steps in a workflow. That’s a lot more capability, and it’s worth being deliberate about what you let it do on its own.
Use Source Control
If you’re using PBIP format, your project files are plain text and work naturally with Git. This becomes especially valuable at this stage: you can have the AI commit its changes after each meaningful step, giving you a clean history you can roll back to if something goes wrong. Treating AI-assisted changes like any other code change — committed, reviewable, reversible — is one of the better habits you can build at this stage. If you struggle to understand Git, you can ask your AI harness to help you.
Customize: Add Your Own Instruction Files
You create markdown files that give your AI persistent, project-specific context about how you work: your conventions, your preferences, your patterns.
Most AI coding tools support some form of instruction file. In Claude Code, it’s CLAUDE.md. In GitHub Copilot, it’s custom instructions in settings. The format varies; the concept is the same.
For Power BI work, your instruction file might include things like:
Your DAX formatting preferences (line breaks, indentation, variable naming)
Your measure organization conventions (measure tables, display folders)
Your model naming standards (for example, human-readable table and column names over technical prefixes or source system names)
Design rules for your reports (color palette, font choices, no pie charts)
How your date table is structured and what the key columns are called
Links to your organization’s style guide or data dictionary
A good instruction file means fewer corrections and more outputs you can actually use.
Rather than putting everything into a single file, consider a lean primary instruction file that describes the project and references separate, focused files: one for DAX conventions, one for report design standards, one documenting your date table, and so on. In Claude Code specifically, this also takes advantage of how context is loaded: referenced files are only pulled in when relevant to the task at hand, rather than everything being loaded upfront. A single bloated instruction file consumes context window space on every interaction whether or not that content is needed. In GitHub Copilot, file inclusion is controlled by applyTo glob patterns in each instruction file, so you get similar control by scoping each file to the relevant context. The CLAUDE.md file can be created and edited manually or by the AI. Once it’s in your project root, the AI picks it up automatically on every interaction with that project.
Bonus: Turn Instructions Into Skills
You package your instruction content into a reusable skill that you can invoke across any project, not just the one where you wrote the file.
Skills are bundles of instructions that activate a specific capability or set of behaviors. Rather than copying your instruction file into every new project, you install the skill once and it’s available everywhere.
Why Skills Beat Generic MCP Servers for Personal Preferences
External MCP servers give your AI tools and data the ability to query an API, read a file, and fetch documentation. What they can’t give it is your preferences. An MCP server doesn’t know that you always put measures in a dedicated table, or that you prefer your cards to have a specific light gray background color, or that you never use the default blue theme.
Skills fill that gap. They capture the preferences and conventions that make your work yours.
A Real Example: Power BI Report Design Skill
I built a Power BI Report Design skill that I use across my projects. It contains:
Design guidelines: My preferred color palettes, typography choices, visual spacing rules, when to use which chart type, accessibility considerations
HTML mockup instructions: Detailed guidance for generating high-fidelity HTML mockups that closely reflect what’s actually achievable in Power BI Desktop, not idealized designs that look great in a browser but can’t be replicated in the tool
That last point matters more than it might seem. When you ask AI to design a report, it can easily generate beautiful HTML that would be impossible to build in Power BI Desktop: a fully custom tooltip on hover, pixel-perfect custom fonts, complex CSS animations. My skill steers the AI away from those dead ends and toward designs that translate cleanly into real Power BI visuals, formatting options, and layout constraints.
The skill also generates a Power BI theme file from the mockup, so the colors and typography translate directly into Desktop without manual configuration.
The result: mockups that set accurate expectations for stakeholders, designs I can actually build, and a theme file ready to apply. I drafted the original instruction files in Claude Desktop, had it package them into a skill, and installed it. Now I just invoke the skill to generate the HTML mockup and theme file.
Putting It Together
You don’t have to climb all five rungs at once. For many Power BI developers, the chat interface delivers real value without the file access risks that come with deeper integration. It’s not a compromise; it’s a real starting point. Master the first layer, and layer on the next when you find yourself bumping into its ceiling (and when you understand the risks and rewards of each step).
Stage
What You Need
What You Gain
Chat interface
A browser or desktop application (Claude)
On-demand expertise, no setup
VS Code + AI extension
VS Code, PBIP format, AI extension
AI sees your code, proposes diffs
Skills + MCP servers
GitHub Copilot CLI, Claude Code, or similar harness
AI takes actions, queries live context
Instruction files
A markdown file in your project
AI learns your conventions
Skills
A skill file installed in your AI harness
Reusable preferences across all projects
At every stage, you decide how much autonomy the AI has and what it has access to. Start where you’re comfortable and dial up the automation only as your trust and understanding of the tradeoffs grow.
https://procuresql.com/wp-content/uploads/2026/06/AI.avif11211478Meagan Longoria/wp-content/uploads/2024/05/Data-Architecture-as-a-Service-with-ProcureSQL.pngMeagan Longoria2026-06-22 19:06:532026-08-21 17:43:20Crawl, Walk, Run with Agentic Development of Power BI Assets
https://procuresql.com/wp-content/uploads/2026/05/761c3eee-6a59-409c-bc29-5ffacc24cd48-2.avif5761024Justin Cunningham/wp-content/uploads/2024/05/Data-Architecture-as-a-Service-with-ProcureSQL.pngJustin Cunningham2026-05-12 21:44:332026-05-12 21:44:41T-SQL Tuesday 198: The Hidden ETL Mistake That Silently Wastes Time And Compute
Materialized lake views (MLVs) in Microsoft Fabric are an effective way to implement medallion architecture declaratively, but once you have a pipeline of MLVs in production, you need visibility into whether they’re current. Fabric’s MLV management area gives you a visual lineage and refresh history, but if you want to build automated alerting, logging, or custom tooling, you need to get that information programmatically. This post walks through one way to do that, using a small demo lakehouse built entirely in a Fabric notebook.
Getting lineage from table properties
When you create a materialized lake view, Fabric automatically populates a table property called fabric.source.entities that describes every immediate upstream source. You can retrieve it with SHOW TBLPROPERTIES and parse the JSON payload:
props = spark.sql(f"SHOW TBLPROPERTIES dbo.mlvc").collect()
source_entities_raw = next(
    (row["value"] for row in props if row["key"] == "fabric.source.entities"),
    None
)
sources = [e["tableName"] for e in json.loads(source_entities_raw)]
The payload includes workspace, artifact, and schema context for each source, which means it can support cross-lakehouse lineage scenarios as that capability matures. Combining this across all MLVs in a schema, using SHOW MATERIALIZED LAKE VIEWS IN dbo, gives you the full dependency graph without any hardcoding.
Getting last modified time from source tables
If you have Change Data Feed enabled on your base Delta tables (which you should for optimal MLV refresh anyway) you can retrieve the timestamp of the last committed operation from the Delta transaction log:
history = spark.sql(f"DESCRIBE HISTORY dbo.table1 LIMIT 1").collect()
last_modified = history[0]["timestamp"]
DESCRIBE HISTORY returns the full transaction log in reverse chronological order. LIMIT 1 gives you the most recent entry, which corresponds to the last time data was written to the table. This is more reliable than file system metadata because it reflects committed Delta transactions, not just file touches.
Getting last refresh time from an MLV
MLVs are persisted as Delta tables under the hood, so the same DESCRIBE HISTORY approach works for them too:
history = spark.sql(f"DESCRIBE HISTORY dbo.mlva LIMIT 1").collect()
last_refresh = history[0]["timestamp"]
This gives you the timestamp of the last time the MLV was successfully refreshed, whether that was triggered by a schedule, a notebook, or manually from the portal.
Detecting staleness
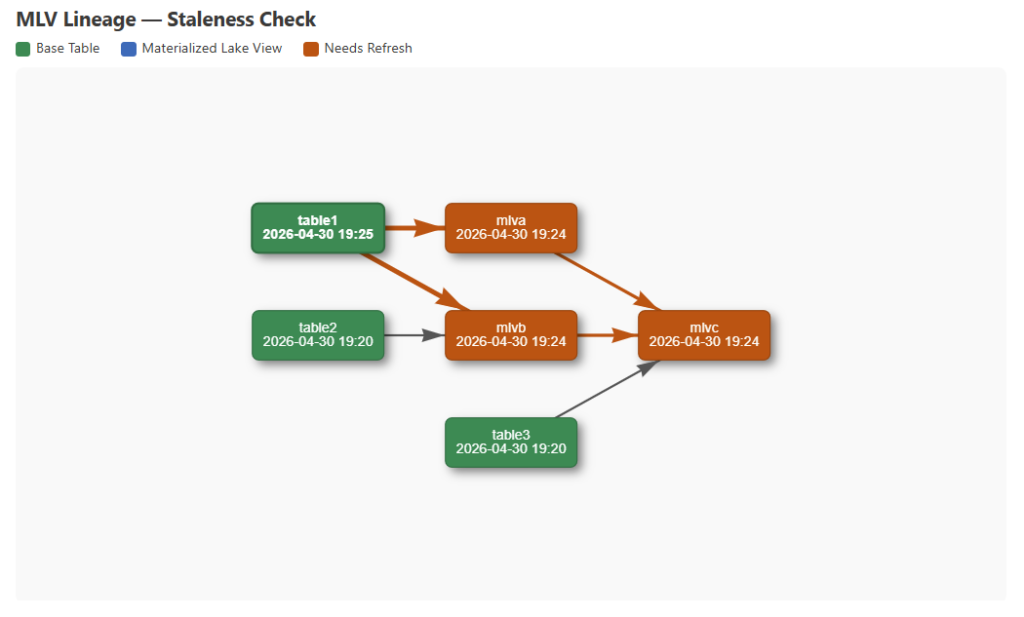
With timestamps for both sources and MLVs in hand, you can compare them to determine whether any MLV is out of date. An MLV is stale if any of its upstream sources have a newer timestamp than the MLV itself. Staleness also propagates downstream — if mlvb is stale, then mlvc which depends on mlvb is also stale regardless of its own source timestamps. From there you can write results to a Delta table for historical tracking, feed them into an alerting pipeline, or visualize them inline in the notebook.
Visualizing dependencies in the notebook
Once you have the lineage graph and timestamps as Python objects, you can render an interactive dependency diagram directly in a Fabric notebook cell using displayHTML. Rather than building the diagram from scratch, I used vis.js, a JavaScript network visualization library that loads directly from a public URL at render time with no package dependencies to manage.
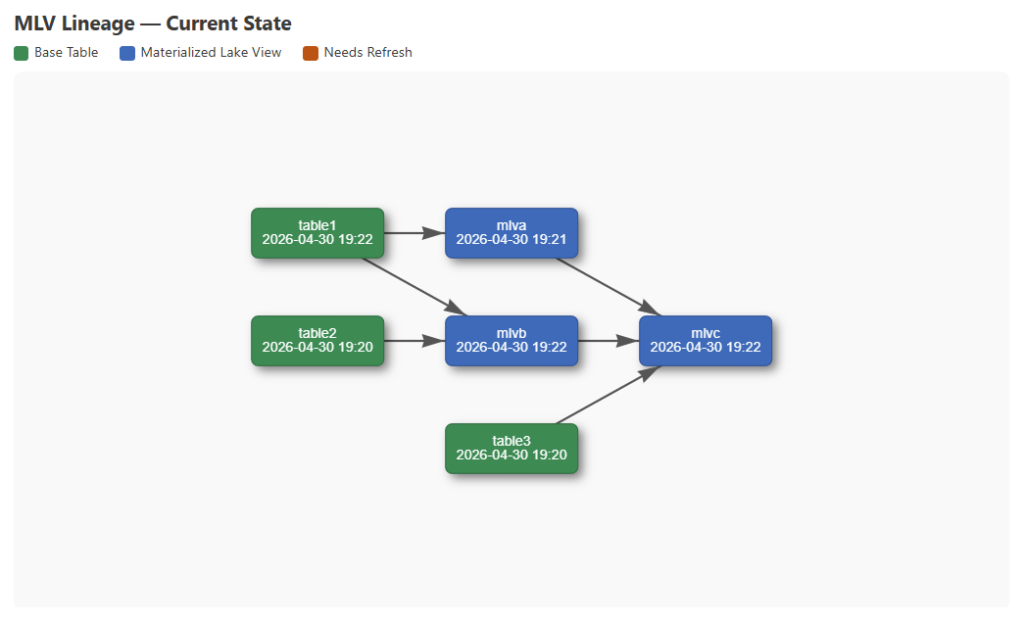
vis.js handles node layout, edge routing, and interactivity out of the box, which makes it a practical choice for notebook-based visualization. The diagram is built by serializing the Python lineage dict and timestamp dict to JSON, injecting them into an HTML string, and passing that to displayHTML. vis.js renders a hierarchical left-to-right layout that mirrors data flow direction, with each node labeled with the object name and its last modified or last refresh timestamp. Nodes are color-coded by type — green for base Delta tables, blue for MLVs — and when staleness detection is enabled, any node that needs a refresh turns orange, as do the edges feeding into it. The resulting diagram is interactive — nodes can be dragged to reposition them, the canvas can be scrolled to zoom, and hovering over a node highlights it and its connected edges, which is useful when tracing dependencies in a more complex pipeline.
One thing worth noting: I attempted to use matplotlib first, which is natively available in Fabric notebooks, but I ran into limitations with arrow routing that made the diagram hard to read when nodes were at different vertical positions. vis.js solved that cleanly without any additional setup, as long as the CDN is accessible from your Fabric capacity.
Walkthrough
To demonstrate this end to end, my notebook sets up three base Delta tables and three MLVs with the following dependencies:
mlva is sourced from table1
mlvb is sourced from table1 and table2
mlvc is sourced from mlva, mlvb, and table3
Change Data Feed is enabled on all three base tables so the Delta transaction log captures each write, and CDF is set on the MLVs as well so incremental refresh is available. After setup, the notebook refreshes all three MLVs in dependency order — mlva and mlvb first, then mlvc — to get a clean baseline. You could also refresh them from the Materialized lake views tab on the Lakehouse item in the Fabric portal.
With everything refreshed, parsing fabric.source.entities and DESCRIBE HISTORY across all objects gives us the full lineage graph and a timestamp for every node. At this point nothing is stale, and the baseline diagram reflects that:
Next, three new rows are inserted into table1. That single write makes table1 newer than mlva, mlvb, and mlvc — all three depend on table1 either directly or through a dependency. Re-fetching timestamps and running the staleness check propagates that through the graph, and the updated diagram highlights all affected nodes:
The Fabric portal already gives you a visual lineage and refresh history for MLVs, but doing this programmatically means you can build on top of it — logging refresh state over time, triggering alerts when MLVs go stale, or embedding a live diagram in an operational notebook. The full notebook is available in my GitHub repo.
What would you do with programmatic access to MLV lineage and refresh state? Let me know in the comments.
There is currently no way to set a default value in a Power BI slicer visual. If you create a report with a slicer for month and choose the current month (e.g. April 2026), save the report, and then come back to the report a month later, your original selection will be enforced and the data will now show the prior month. So how do you make reports with slicers show data for the current month by default while allowing users to select other months as needed? This video shows 3 options. My current personal favorite is the button slicer solution I show as the third option.
https://procuresql.com/wp-content/uploads/2026/04/Screenshot-2026-04-10-114049.avif11051952Meagan Longoria/wp-content/uploads/2024/05/Data-Architecture-as-a-Service-with-ProcureSQL.pngMeagan Longoria2026-04-10 18:07:362026-04-10 18:07:47New Video: Defaulting Power BI Slicers to the Current Month
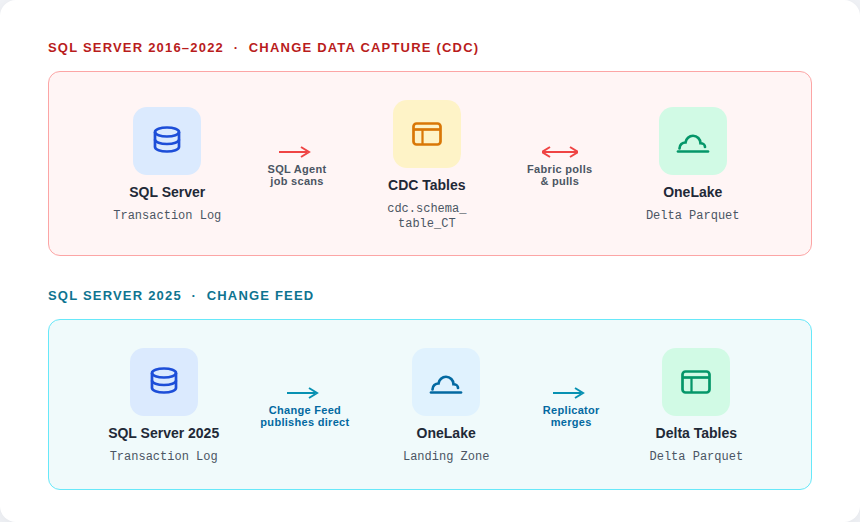
I previously wrote about how the underlying technology for Fabric mirroring changed with SQL Server 2025. The latest version of mirroring that uses the SQL Server Change Feed is reading from the database transaction logs and pushing the data to a landing zone in OneLake. The data is then merged into the Delta tables for the Fabric mirrored database.
In this blog post, we will look at how to monitor this process, both in SQL Server and in Fabric.
Monitoring in the Fabric Portal
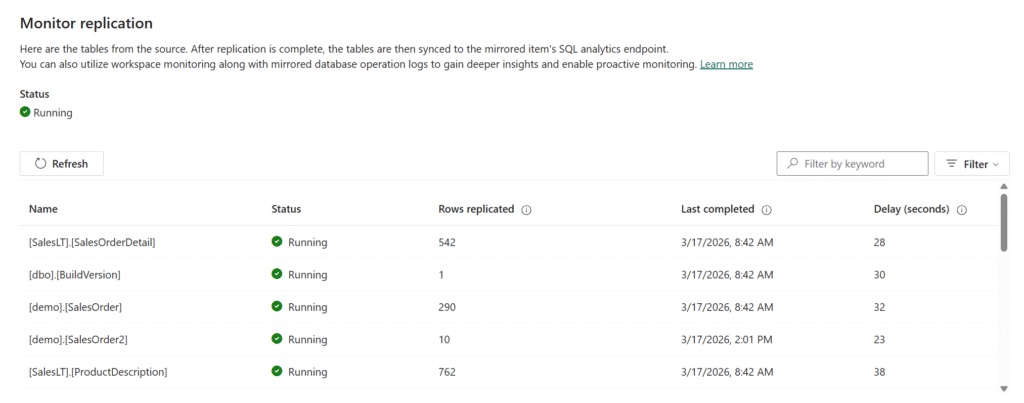
The item page for the mirrored database in the Fabric portal shows replication status for the database overall as well as for each table. The per-table status includes:
rows replicated: the cumulative count of replicated rows, including all inserts, updates, and deletes applied to the target table
last completed: the last time the mirrored table was refreshed from the source
delay (seconds): the time between when a change was committed at the source and when it was successfully applied to the destination
It is possible for the overall database status to show “Running” while a specific table has an issue. The last completed date will typically reflect the last time data in the table changed — if nothing has changed, nothing is sent and the date does not update. The delay is tracked on the database side and sent to Fabric for display on the monitoring page.
Monitoring in the Database
When you configure Fabric mirroring, it enables the change feed on the database and the tables you have selected to mirror. Once everything is configured, there are some system views and stored procedures you can access to see what’s going on.
sys.dm_change_feed_log_scan_sessions
This DMV is your primary window into change feed health and activity. It returns one row per log scan session, plus an aggregate row where session_id = 0 that summarizes all sessions since the instance last started. The aggregate row is useful for understanding overall health since the instance last started; the individual session rows show you what’s happening in discrete scans.
You want to see sessions completing without errors, with tran_count incrementing and currently_processed_lsn or currently_processed_commit_lsn advancing over time. If sessions are stalling at the same batch_processing_phase repeatedly, or error_count is climbing, something needs attention.
The schema_change_count column tracks DDL-related log records processed in a session. Note that this is not a 1:1 mapping with the number of DDL operations — some operations, like adding, altering, or dropping a column, generate two log records per operation, so the count may be higher than you expect.
sys.dm_change_feed_errors
When error_count in the sessions DMV is non-zero, this is where you find out what went wrong. Some errors are transient and will resolve on their own; others won’t. Repeated errors of the same type are a signal to investigate rather than wait it out.
sys.sp_help_change_feed
This stored procedure gives you a configuration-level view of which tables are enrolled in mirroring and their current state. It’s useful after initial setup to confirm everything was picked up correctly, and when a table stops replicating and you want to verify it’s still enrolled.
sys.databases
Unlike CDC, the change feed doesn’t write to change tables in the source database, so it won’t directly cause the transaction log to grow. However, it does hold log truncation until changes are successfully replicated to Fabric. You can use is_data_lake_replication_enabled = 1 to filter sys.databases to only the databases where Fabric mirroring is enabled. A value of REPLICATION for log_reuse_wait_desc means mirroring is currently holding log truncation — not necessarily something that needs immediate action, but if log usage is also growing, that’s a signal that mirroring may not be keeping pace and warrants investigation. If the log hits its size limit, writes to the database will fail.
Extended Events
Microsoft also provides an extended events session you can use for deeper troubleshooting. The session captures change feed activity including errors, snapshots, performance, and scheduler events. Because it can be verbose, Microsoft recommends only running it when you’re actively troubleshooting a problem rather than leaving it on all the time. You can find the session definition in the Troubleshoot Fabric Mirrored Databases from SQL Server documentation.
Files in OneLake
You can use Azure Storage Explorer to browse the files for your Fabric mirrored database.
The Monitoring folder contains two files:
tables.json shows each mirrored table along with its status, any error message, and metrics.
replicator.json shows the overall database replication status along with any error message.
The Manifest_1.json file in the LandingZone folder is a newline-delimited JSON log that records everything the change feed has published to OneLake — initial snapshots, incremental change batches, DDL events, and table creation notifications. It’s not something you’d monitor routinely, but it’s useful for troubleshooting — for example, to confirm that a snapshot completed and how many rows were captured, to see whether incremental batches are being written, or to trace when a DDL change occurred and verify that a re-snapshot was triggered as a result.
Within each table’s subfolder you’ll find a TableSchema.json file with the table’s schema definition, a FullCopyData folder where the initial snapshot parquet files are written, and a ChangeData folder where incremental CSV change files land after the snapshot completes. If you’re troubleshooting a data discrepancy or want to confirm that specific changes have made it to OneLake, you can browse these folders directly to check whether the expected files are present.
Knowing Where to Look
For day-to-day health checks, the portal monitoring page and sys.dm_change_feed_log_scan_sessions will cover most of what you need. If you see errors or stalled sessions, sys.dm_change_feed_errors and sys.sp_help_change_feed are the next stop. The OneLake files and extended events are there when you need to dig deeper into a specific problem. Mirroring continues to get new features and changes, so keep an eye on the Microsoft Fabric Mirrored Databases from SQL Server documentation for updates.
The post Monitoring Fabric Mirroring for SQL 2025 first appeared on Data Savvy.
Mirroring of SQL Server databases in Microsoft Fabric was first released in public preview in March 2024. Mirrored databases promise near-real-time replication without the need to manage and orchestrate pipelines, copy jobs, or notebooks. John Sterrett blogged about them last year here. But since that initial release, the mechanism under the hood has evolved significantly. Let's talk about Fabric Mirroring: Change Feed vs CDC Explained.
How Fabric Mirroring Works in SQL Server 2016–2022 (CDC)
When mirroring was first released for Azure SQL Database, it used Change Data Capture (CDC). That is still what is used to mirror SQL Server 2016 – 2022.
CDC works by asynchronously scanning the transaction log to find changes related to tracked tables, then writing those changes to dedicated change tables — one per tracked source table, in the format cdc.schema_tablename_CT. A SQL Server Agent job (sys.sp_cdc_scan) is responsible for that log scan and write. Fabric’s replication layer then polls those change tables and pulls changes into OneLake, where they’re converted to Delta Parquet format. The result is a two-hop process: log → change table → OneLake. That intermediary write step is where the overhead lives. If you have a busy SQL Server, this overhead may not be acceptable.
Setting up CDC for SQL Server 2016–2022 requires the fabric_login principal to be a member of the sysadmin server role, at least temporarily, and any future CDC maintenance also requires sysadmin membership. For security-conscious organizations, that’s a significant ask. You can drop the login from sysadmin after CDC is configured, but having to elevate it in the first place causes friction.
In SQL Server 2016–2022, if a table’s schema changes after CDC is enabled, the mirrored table schema no longer matches the source, and mirroring fails. Getting replication back on track requires manually disabling and re-enabling CDC on the affected tables.
SQL Server 2025 Fabric Mirroring: The Change Feed Explained
SQL Server 2025 has a much better solution: the change feed. Rather than routing changes through change tables, the change feed scans the transaction log at a high frequency and publishes committed changes directly to a landing zone in OneLake. Fabric’s replicator engine then merges those files into the target Delta tables. The intermediary write step is gone.
Because the change feed doesn’t write data back into the source database, it carries lower overhead than CDC. There are no change tables to maintain, no SQL Server Agent jobs to keep healthy, and no cleanup jobs running in the background purging old change records. For busy OLTP systems where CDC’s performance overhead was a concern, this is a meaningful improvement.
DDL changes are handled better, too. Rather than failing when a schema change is detected, the change feed triggers a full re-snapshot of the affected table and reseeds the data automatically. That re-snapshot has a cost if the table is large, but it’s self-healing. You won’t come in Monday morning to find mirroring has been broken since Friday’s deployment.
The permissions model is also cleaner. Rather than requiring sysadmin elevation to configure CDC, SQL Server 2025 mirroring uses a system-assigned managed identity to handle outbound authentication to Fabric. You still create a dedicated login with minimal permissions on the source database, but sysadmin is never required.
How to Plan Your Fabric Mirroring Migration: CDC vs Change Feed
CDC-based mirroring is still what SQL Server 2016–2022 uses, and it works. Just go in with eyes open about the performance overhead, the sysadmin requirement, and the DDL limitations.
If you’re already on SQL Server 2025 or planning to upgrade, the change feed makes mirroring a more attractive option than it was under CDC — particularly for busy OLTP systems where the overhead of change table writes was a concern.
Before you enable mirroring on SQL Server 2025, there are a few constraints worth knowing. The source database must be set to the full recovery model (simple recovery is not supported). The change feed is also mutually exclusive with CDC: if CDC is already enabled on a database, you cannot enable Fabric mirroring on that same database. If you’re running CDC today for other consumers, you have a decision to make. You’ll need to decide whether to remove CDC and consolidate on the change feed or keep CDC and find another path for getting that data into Fabric.
Note: As of March 11, 2026, SQL Server 2025 mirroring is supported for on-premises instances only. It is not supported for SQL Server 2025 running in an Azure Virtual Machine or on Linux. It also requires the instance to be connected to Azure Arc with the Azure Extension for SQL Server installed.
Mirroring is still evolving, so it’s worth keeping an eye on the Fabric Mirroring roadmap. And of course, stay tuned for announcements from FABCON next week!
 Crawl: Ask Questions in an AI Chat Interface
 Walk: Bring AI Into Your Code Editor
 Run: Add Skills and Connect to MCP Servers
 Customize: Add Your Own Instruction Files
 Bonus: Turn Instructions Into Skills
 Putting It Together